CollabDocs | Real-Time Collaborative Editor
Mar 2026 – May 2026
541 ops/sec
p95 1.22ms latency
140+ MAU
Built a real-time collaborative editor with a custom Operational Transformation (OT) engine in C++17, verified zero divergence across 500 randomized concurrent-edit trials. Designed high-performance WebSocket server using Boost.Asio with strand-serialized write queues and op broadcast batching.
C++17Boost.AsioWebSocketsOperational TransformationMultithreadingCMakeDockerAntiGravity
LogAI Engine | High-Throughput Telemetry Classifier
6,300+ logs/sec
99.69% coverage
p50 0.019ms
Built a 3-tier log classifier (Regex → BERT/ONNX → Mistral-7B) processing 2M logs at 6,300+ logs/sec. Applied LRU cache on LLM dispatch path resolving 4,528 of 6,117 LLM-routed logs without live API calls. Diagnosed and fixed CPU starvation under batch load.
PythonBERTONNXMistral-7BRegexGradioConcurrency
KVInfer – GPT-2 Inference Engine
Nov 2025 – Mar 2026
18.7 tok/s
TTFT 847ms
14 concurrent sessions
Engineered a C++ GPT-2 inference engine with SIMD and parallelism. Architected a multi-engine process pool with KV-cache and LRU eviction, sustaining 14 concurrent sessions within 8GB/16GB RAM.
C++SIMDFastAPIDockerLLM Inference
C++ Inference Engine for 50M GPT Model
Nov 2025 – Feb 2026
28.12 tok/s
35.57ms/token
61% latency reduction
CPU-optimized C++ inference engine for a 51M-parameter GPT model, achieving 28.12 tokens/sec on an Intel i3-12th Gen CPU. Reduced per-token latency 91.87ms → 35.57ms by eliminating heap allocations and parallelizing with OpenMP & AVX2/FMA kernels.
C++PythonFastAPIOpenMPAVX2/SIMD
C++ High-Performance Order Matching Engine
Aug 2025 – Jan 2026
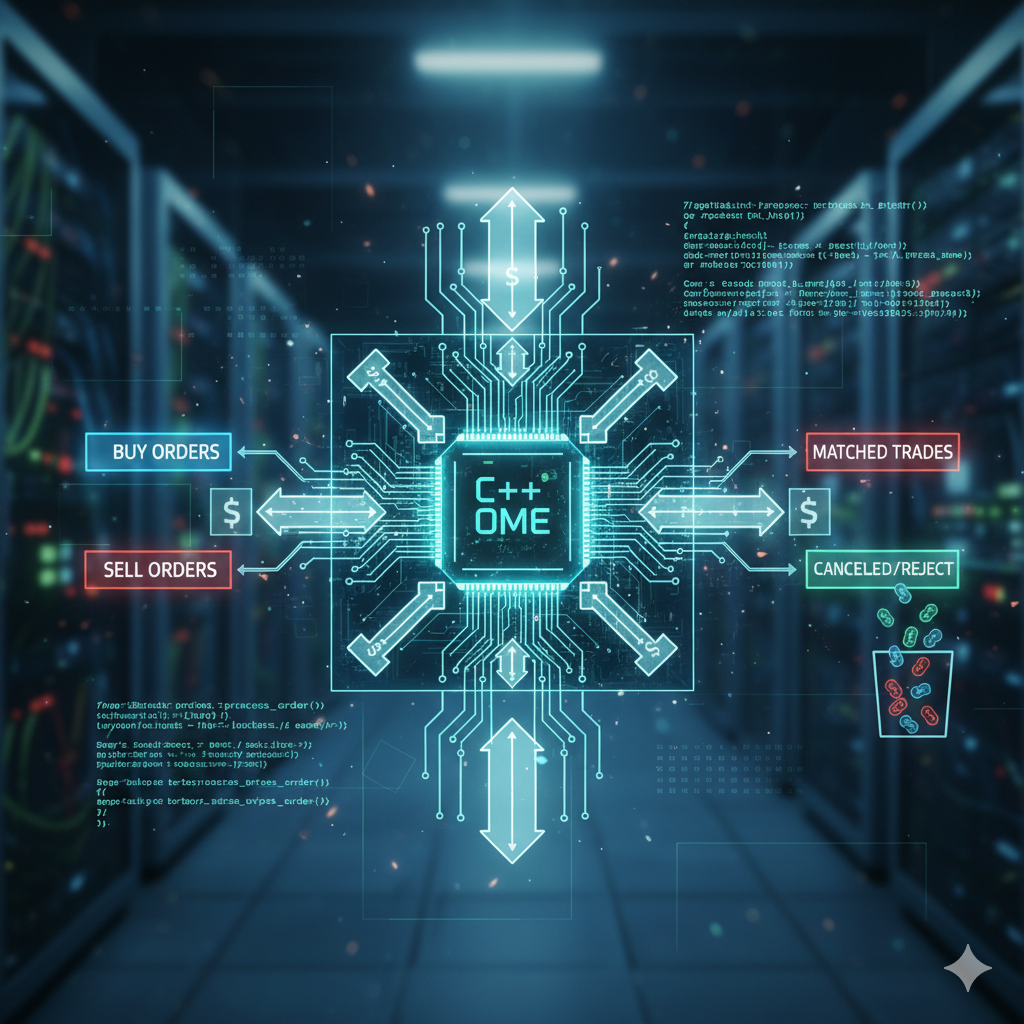
53K+ orders/sec20K orders in 375ms
Engineered a robust Order Matching Engine in C++20 using std::map for strict price-time priority and std::unordered_map for O(1) lookups. Validated with a comprehensive GoogleTest framework.
C++20STLMultithreadingGoogle Test
Custom-Trained SQL Small Language Model (10M GPT)
Sep 2025 – Oct 2025
Architected a compact 10M-parameter GPT model from scratch in PyTorch. Implemented mixed-precision and gradient accumulation, reducing per-epoch data loading times by over 90%.
PyTorchTransformersMixed-Precision10M Params
ContextEngine: RAG System
Built a full RAG pipeline (BM25 + FAISS) boosting grounded accuracy (42%→71%). Optimized inference using vLLM.
RAGvLLMFAISS
Real-Time Event Stream
Designed an event-driven pipeline for e-commerce data using asynchronous producers/consumers.
KafkaDockerPython
Memory-Efficient Fine-Tuning
Implemented a QLoRa (4-bit) pipeline, reducing memory footprint by ~70% on a single T4 GPU.
QLoRaLLMPyTorch
AI Coder Buddy
AI agent using LangChain that plans and generates multi-file applications, decreasing development cycle time by 30%.
LangChainGroq APIAI Agents
Credit Risk Model
Developed interpretable ML models that improved prediction accuracy by 20% for NBFC clients.
Scikit-learnStreamlitMLOps
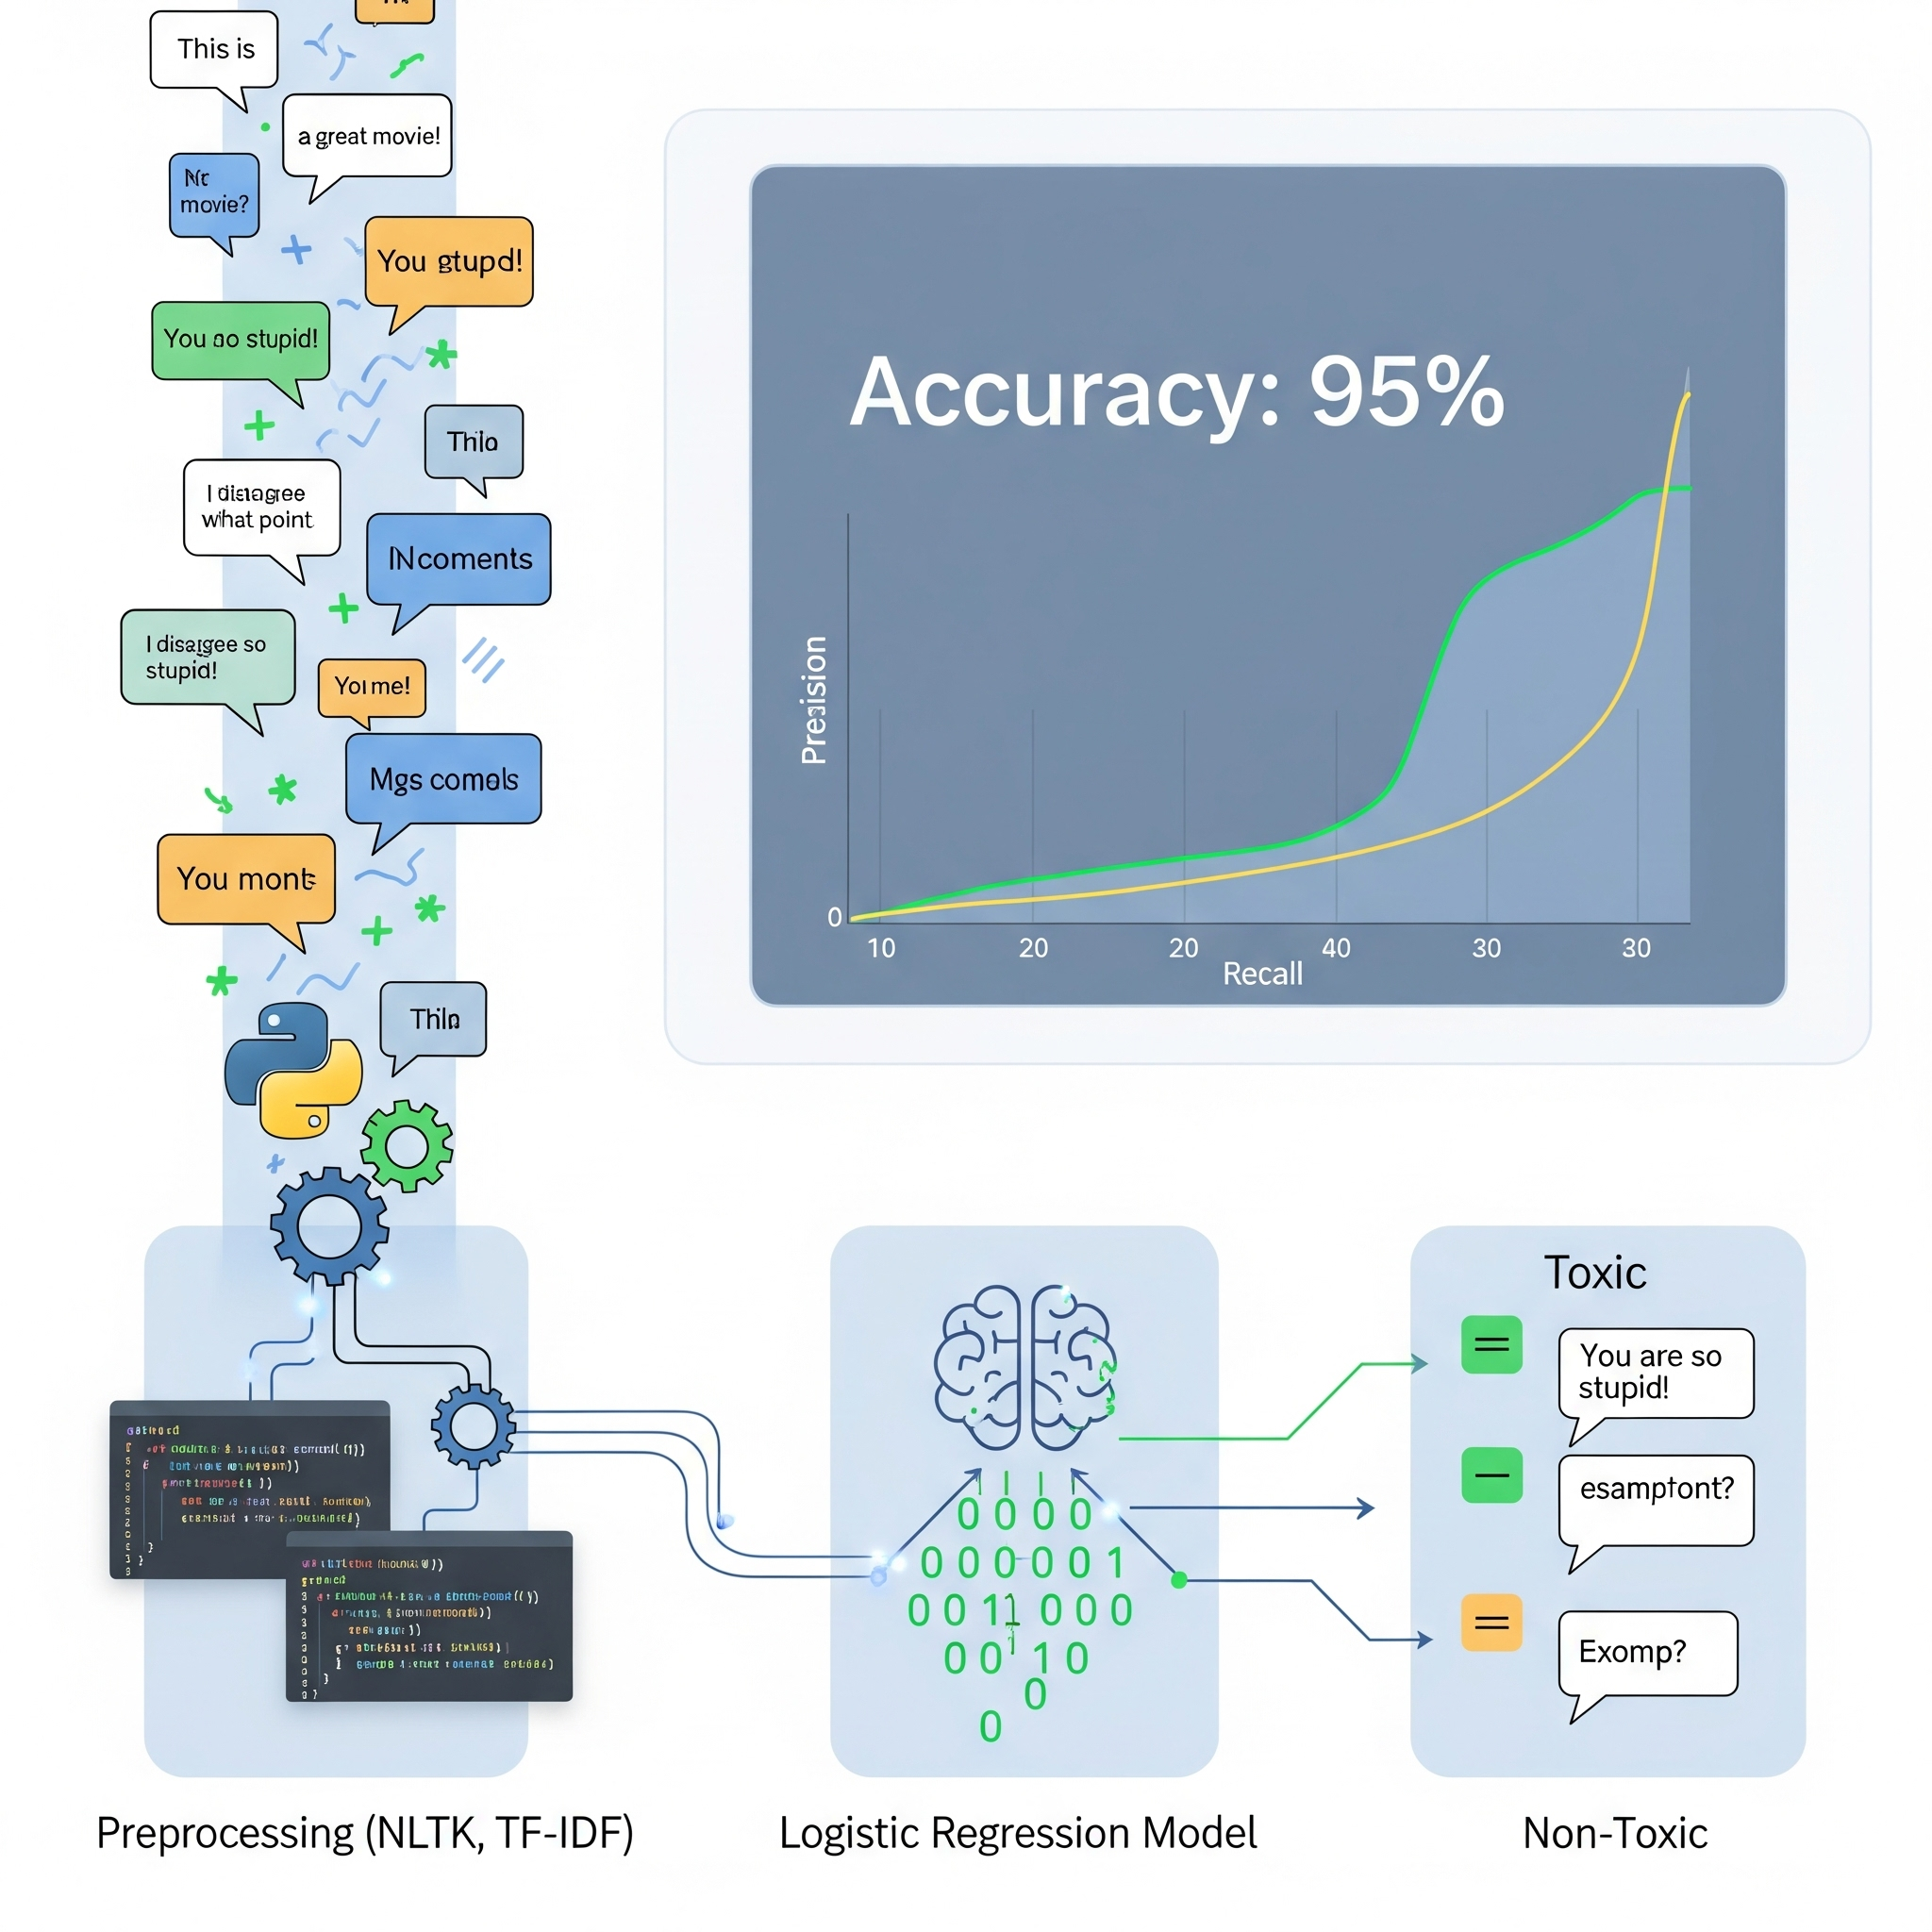
Toxic Message Detector
Trained a text classification model with TF-IDF on 100K+ comments, achieving 95% accuracy.
NLTKTF-IDFPandas
Multi-Modal Crew AI
Designed a multi-agent framework that automates market research by 70% using specialized 'Researcher' and 'Writer' agents.
Gemini APILangChainStreamlit